Dana Meier · 15 September 2026
Analyzing Performance Tracking Methods in Unique Software Environments for Web Professionals
Web professionals routinely examine performance tracking methods that adapt to unique software environments such as serverless architectures, edge computing nodes, and container orchestration systems, where traditional monitoring approaches often require substantial adjustments to capture accurate data across distributed components. These environments generate complex telemetry streams that demand specialized collection techniques, including distributed tracing protocols and real-time metric aggregation, while researchers continue to refine algorithms that correlate events across multiple runtime layers without introducing latency overhead.
Core Components of Performance Tracking in Customized Setups
Unique software environments present distinct challenges because they combine dynamic scaling behaviors with heterogeneous infrastructure layers, so professionals deploy application performance management tools that integrate with cloud provider APIs to pull metrics directly from virtual instances and function executions. Data indicates that combining log aggregation platforms with synthetic monitoring scripts allows teams to reconstruct user sessions across ephemeral resources, whereas isolated error tracking often misses cascading failures that originate in upstream service meshes. Observers note that instrumentation libraries must support multiple programming languages and runtime versions simultaneously, which enables consistent measurement of response times, error rates, and resource utilization even when code deploys change daily.
Evaluating Distributed Tracing and Metric Collection Techniques
Distributed tracing frameworks capture request flows through microservice chains by propagating context identifiers, and studies show these identifiers help reconstruct latency contributions from each hop without requiring centralized coordination points. Professionals frequently combine open-source tracing standards with proprietary extensions that add custom attributes for business-specific key performance indicators, while automated sampling strategies reduce storage costs yet preserve statistical validity for anomaly detection. Research indicates that metric collection agents operating at the kernel level provide higher-resolution data on CPU scheduling and network packet handling compared with user-space alternatives, although integration complexity rises when environments span multiple cloud regions and on-premises clusters.
Adapting Tools for Serverless and Edge Deployments
Serverless platforms limit visibility into underlying execution contexts, so tracking methods shift toward platform-native logging streams and invocation duration reports that feed into centralized analytics pipelines. Edge nodes introduce additional variables because geographic distribution affects network round-trip measurements, and figures reveal that latency percentiles collected from regional points of presence require weighted averaging to produce meaningful global performance baselines. Professionals integrate these sources using query languages that join time-series data with geographic metadata, which supports root-cause analysis when regional outages coincide with traffic spikes. According to documentation from the National Institute of Standards and Technology, standardized telemetry schemas improve interoperability between monitoring vendors and custom internal systems, reducing the effort needed to maintain dashboards that reflect real conditions across hybrid deployments.
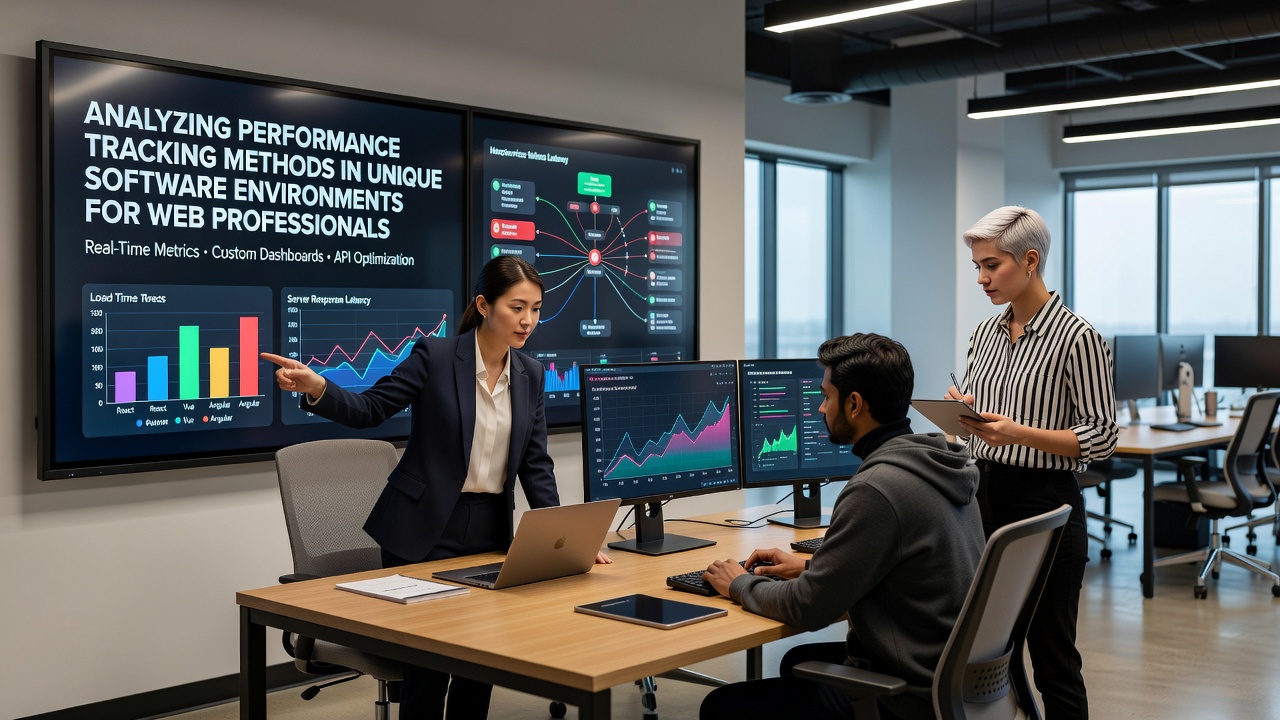
Containerized workloads benefit from sidecar proxies that expose service-level metrics, and these proxies allow granular observation of inter-pod communication patterns without modifying application source code. Those who maintain large Kubernetes clusters report that combining Prometheus-style scraping with event-driven alerting creates faster incident response cycles than legacy polling methods alone, whereas long-term trend analysis still relies on aggregated data warehouses that store historical baselines for capacity planning purposes.
Comparative Analysis of Monitoring Approaches Across Environments
Performance tracking methods diverge sharply when moving from traditional virtual machines to fully serverless or edge-native configurations, since the former permit direct agent installation while the latter depend on exported platform events. Comparative evaluations conducted by academic research groups demonstrate that hybrid approaches, which layer infrastructure metrics with application-level traces, yield the most complete picture of system behavior under varying load profiles. Data from the European Union Agency for Cybersecurity highlights that consistent encryption of telemetry streams protects sensitive operational information during transit between edge locations and central analysis platforms, and this requirement influences both tool selection and data retention policies. Professionals therefore evaluate solutions based on support for encryption standards, query performance at scale, and the ability to export data to external business intelligence systems without custom adapters.
Developments Anticipated by September 2026
By September 2026, updates to open telemetry specifications are expected to standardize additional context fields for AI-driven inference workloads, enabling more precise attribution of compute costs and latency contributions within mixed environments. Industry reports from the Australian Cyber Security Centre indicate growing adoption of privacy-preserving aggregation techniques that allow organizations to share performance benchmarks without exposing proprietary traffic patterns. These advancements support collaborative troubleshooting across vendor boundaries while maintaining compliance with regional data protection frameworks, and they encourage further refinement of sampling algorithms that balance insight depth against transmission overhead.
Conclusion
Performance tracking in unique software environments continues to evolve through integration of distributed tracing, platform-native logging, and standardized telemetry schemas that accommodate serverless, containerized, and edge deployments. Web professionals rely on these combined methods to maintain visibility into system behavior, and ongoing standardization efforts through September 2026 will further enhance interoperability and analytical capabilities across diverse infrastructures.